Skip to content

Home / Services

Service 03 / AI servers

Optimised AI workstations, on your premises.

We maximise the potential of your infrastructure or deploy AI directly on your premises.
Let’s talk about your project Our workstations

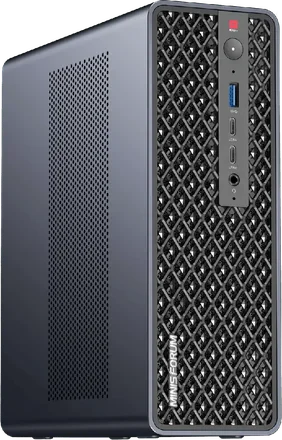
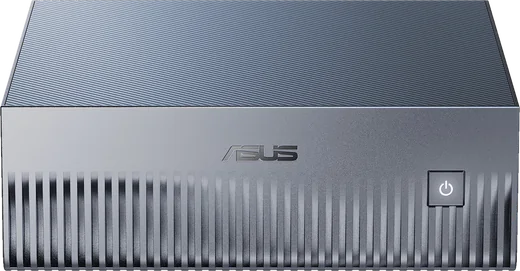
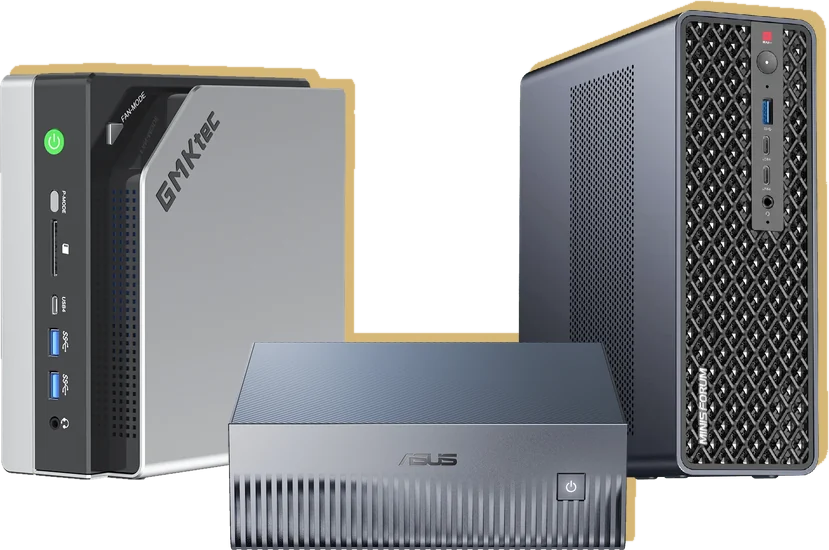
GMKtec EVO-X2, Minisforum MS-S1 MAX and ASUS Ascent GX10 (NVIDIA DGX Spark) AI workstations
  1. 01

    Process your most confidential data

    The AI runs on an isolated workstation on your premises: your data never leaves it.

  2. 02

    Costs divided by 10

    Compared with Claude or ChatGPT, for comparable use.

  3. 03

    Total agility

    To fit every business line: models, tools and interfaces tuned team by team.

Use cases

Business uses, on your own data.

Document search, business software, code: AI workstations work alongside your teams every day.

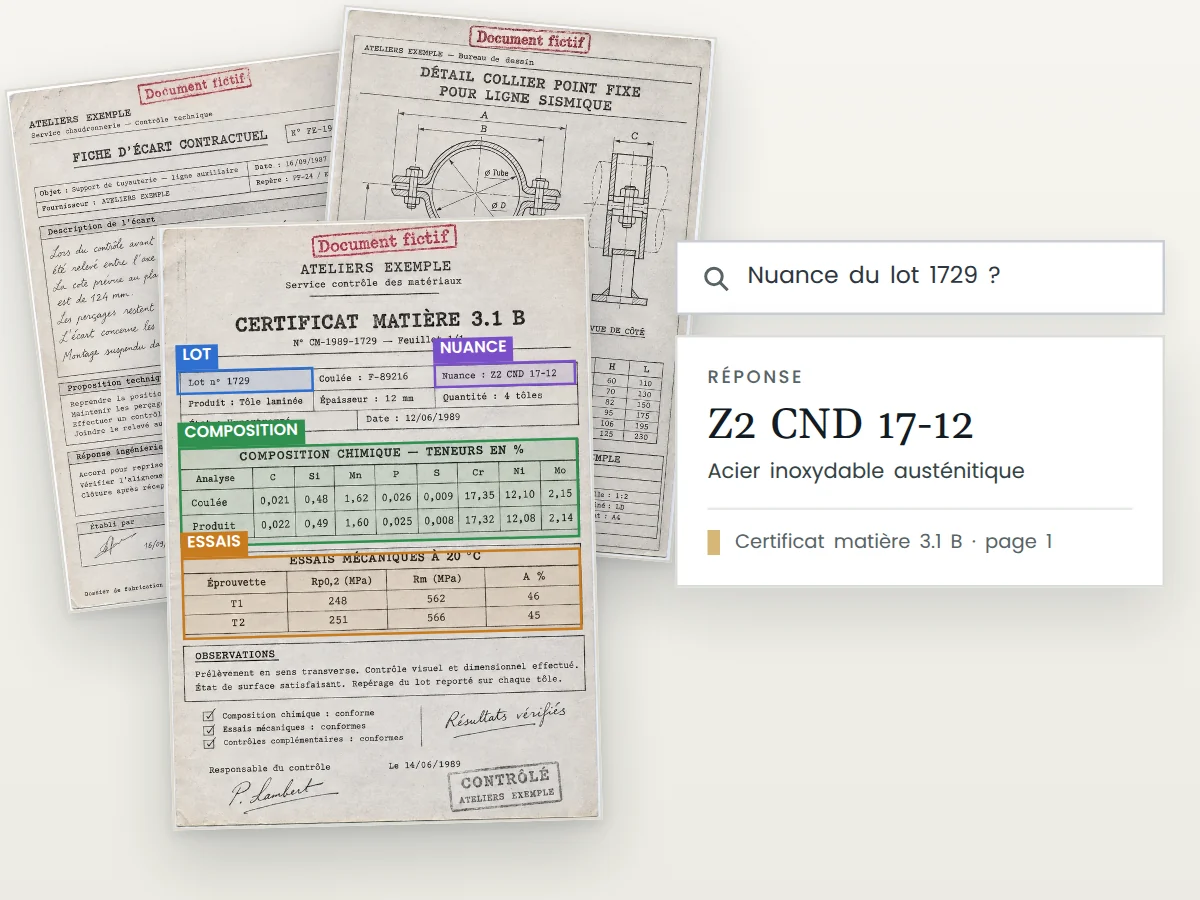
  1. Fictitious mock-up: scanned archive pages labelled by AI and an answer with its source 01

    Document search

    Drawings, forms and scanned archives are read, labelled and made searchable: every answer cites its source.

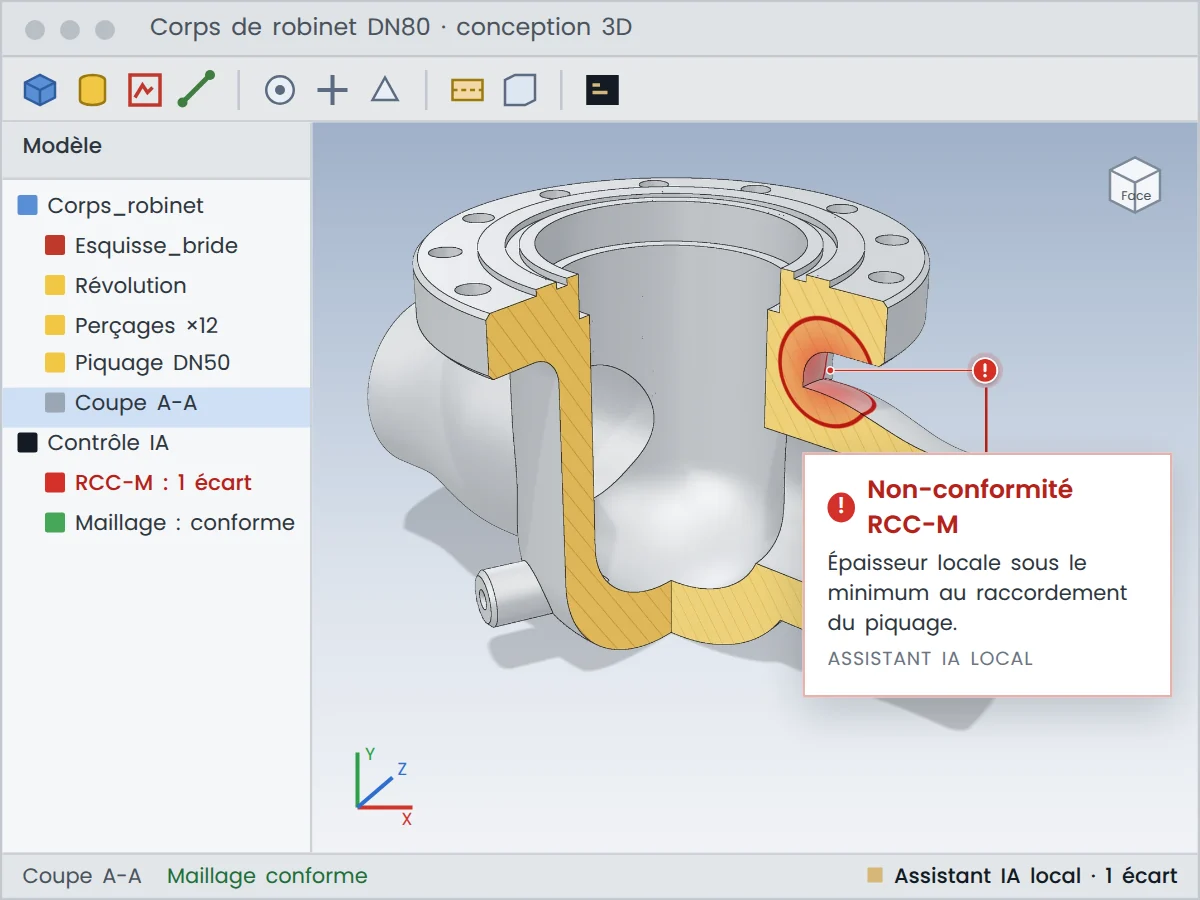
  2. Fictitious mock-up: CAD software where the AI assistant flags an RCC-M non-conformity on a part 02

    Business software

    AI plugs into your software, such as CAD: it checks a part against the applicable code and flags deviations.

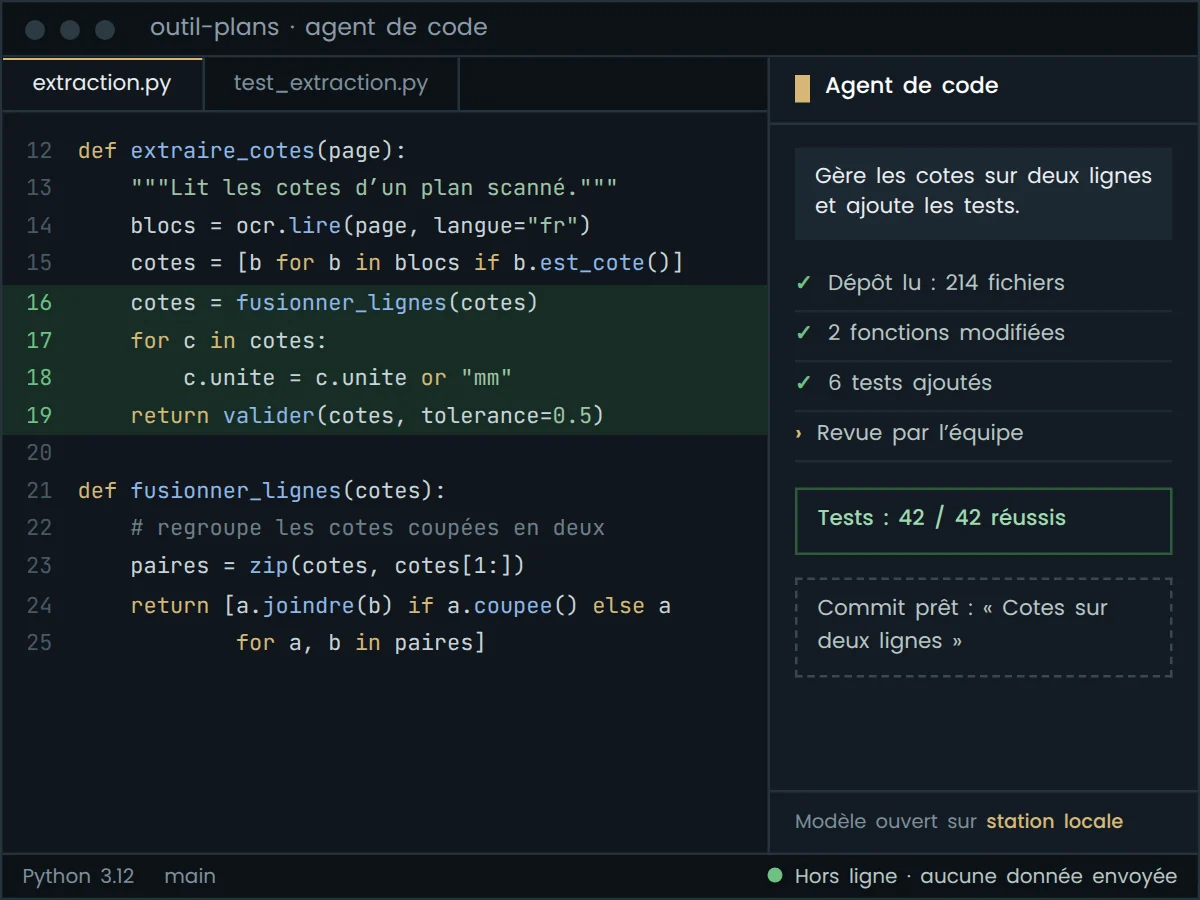
  3. Fictitious mock-up: code editor and coding agent on a local workstation, tests passing 03

    Code writing

    A coding agent writes, tests and documents alongside your developers, without a single line leaving your premises.

Turnkey AI workstation

The right hardware for every use.

Rental or purchase, installation and maintenance of a dedicated, isolated and secure AI workstation on your premises. You retain control of your data.

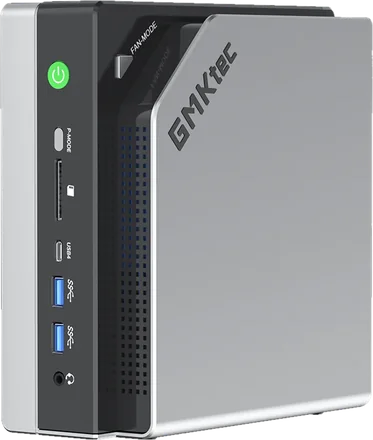
  • GMKtec EVO-X2 AI workstation

    AMD

    GMKtec EVO-X2

    64 GB of unified memory

  • GMKtec EVO-X2 AI workstation

    AMD

    GMKtec EVO-X2

    128 GB of unified memory

  • Minisforum MS-S1 MAX AI workstation

    AMD

    Minisforum MS-S1 MAX

    192 GB of unified memory

  • ASUS Ascent GX10 AI workstation (NVIDIA DGX Spark)

    NVIDIA

    DGX Spark

    ASUS Ascent GX10

    128 GB of unified memory

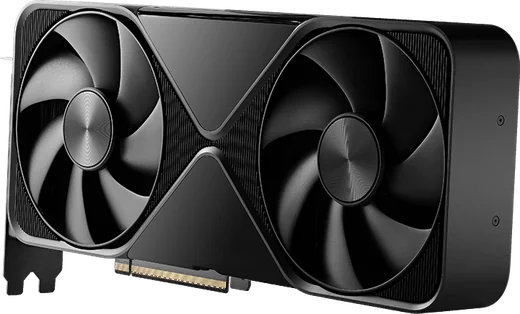
  • NVIDIA RTX PRO 6000 Blackwell graphics card

    NVIDIA

    RTX PRO 6000

    Blackwell graphics card

    96 GB of GDDR7 memory

And other configurations, sized to your needs.

Total control

Total control of your AI workstations.

Models, harness, security: every building block is chosen, tuned and maintained for your business lines.

On your premises

  1. 04

    Business uses

  2. 03

    Harness

  3. 02

    Models

  4. 01

    AI workstation

Security

An isolated and secure workstation. Tailored cybersecurity risk analysis (EBIOS RM).

Optimising your servers

Autoresearch speeds up your existing hardware.

Our MLOps pipeline (quantisation, batching…) gets the most out of the best AI models on your existing hardware.

Our autoresearch agents run dozens of experiments on it autonomously: every optimisation is measured, and only those that speed up the model without degrading its answers are kept.

Faster AI keeps pace with the business: speed is what drives adoption.

×1.52
faster in 24 h
86.5
tokens per second, up from 57.1
11 of 28
experiments kept
Generation speed over the autoresearch runFrom 57.1 to 86.5 tokens per second over 28 experiments run in 24 hours, 11 of them kept.607080900510152025experiment no. →tokens / s ↑no. 2 · failed to start · fast loader (missing scales)no. 3 · discarded · torch.compile · 59.8 tokens / sno. 5 · discarded · fused HyperConnections in BF16 · 58.9 tokens / sno. 9 · discarded · MXFP8 target head (below threshold) · 68.8 tokens / sno. 13 · discarded · NVFP4 target head (fidelity loss) · 79.2 tokens / sno. 15 · discarded · containers pinned to X925 cores · 78.6 tokens / sno. 16 · discarded · host path fixes (below threshold) · 78.8 tokens / sno. 17 · discarded · static expert permutation (below threshold) · 79.4 tokens / sno. 18 · failed to start · expert replicas (missing layer)no. 19 · failed to start · expert replicas (communicator)no. 22 · failed to start · expert replicas (NCCL barrier)no. 23 · discarded · 32 replicated experts (narrowly rejected) · 87.6 tokens / sno. 25 · failed to start · fused router and top-kno. 26 · discarded · MTP with 4 drafts · 86.9 tokens / sno. 27 · discarded · 16k chunked prefill · 86.5 tokens / sno. 28 · discarded · Marlin MXFP8 W8A16 · 86.9 tokens / sno. 29 · discarded · multi-stream expert replicas · 88.4 tokens / sno. 24 · full stack measured · all kept optimisations, measured together · 86.5 tokens / sno. 0 · start · starting recipe · 57.1 tokens / sno. 1 · kept · one-shot all-reduce over RoCE · 60.1 tokens / sno. 4 · kept · fast loader: start-up 594 → 200 s · 60.1 tokens / sno. 6 · kept · MXFP8 HyperConnections, fused kernel · 63.3 tokens / sno. 7 · kept · NVFP4 draft head · 66.0 tokens / sno. 8 · kept · probabilistic drafting · 68.5 tokens / sno. 10 · kept · one-shot all-gather · 69.6 tokens / sno. 11 · kept · probabilistic drafting + NVFP4 logits · 74.0 tokens / sno. 12 · kept · HyperConnections as GEMV + PDL · 74.9 tokens / sno. 14 · kept · FP8 target head, Triton GEMV · 78.5 tokens / sno. 20 · kept · 4-bit GDN recalibrated with GPTQ · 84.6 tokens / sno. 21 · kept · small kernel fusion · 86.3 tokens / s57.186.5
  • best configuration
  • kept
  • discarded
  • failed to start
  • full stack measured

Autoresearch on Qwen 3.8 Flash, two NVIDIA DGX Spark, 24 h unattended.

Case studies
Orano

Nearly ten AI workstations deployed

NVIDIA DGX Spark and AMD workstations, installed and optimised on the client’s premises.

Deployment environment

  • Secure on-premises AI workstations
Confidential engagement

Public sector organisation

5 times as many cases processed

Optimisation of a quantised model for technical and legal drafting tasks. Delivered in 8 weeks.

Deployment environment

  • Installation and rental of a secure on-premises server

Your next step

Which AI use case do you want to build and secure?

Combine AI and cybersecurity to harness the full potential of AI without compromising your data.